“Slop” gets used as a synonym for “made with AI”, which makes it useless as a warning. It actually names two separate failures, and you can commit either one on its own. A video can be technically flawless and still be slop. A video can have a visible generation artefact in it and be fine.
The first failure is at the artefact level: the thing looks wrong, in specific documented ways that viewers detect without being able to name. The second is at the authorship level: nothing in it required you. Platforms enforce the second one. Audiences punish both, and they punish the second one harder.
The artefact checklist#
These are the failure modes current models have not solved, in rough order of how quickly a viewer notices. Each one has a fix that costs almost nothing.
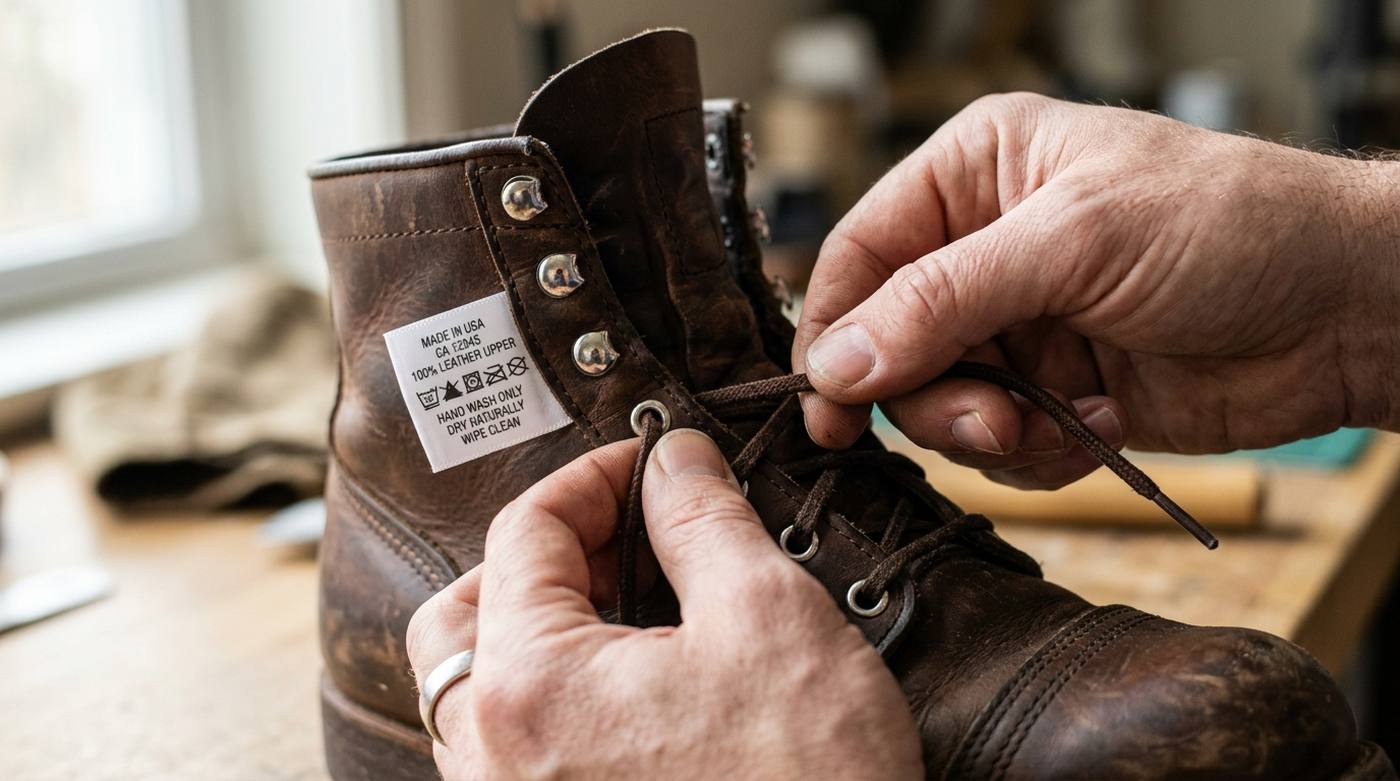
Text and logos. This was the most reliable tell and it is decaying fast — the specimen above renders six lines of label copy correctly. Treat it as a risk rather than a certainty: rendering still degrades on anything moving, so a label on a spinning bottle will garble where a static one now often will not. Never ask the model for text you need read, and composite real type over the top in the edit. A label on a rotating bottle looks plausible in one frame and turns to nonsense across the rest. Never ask the model for text you need read. Composite real type over the top in the edit, and if a brand mark has to appear on a product, film the product or overlay the mark.
Hands doing something. Also decaying as a tell: the specimen has two correct hands. What survives is the logic of what the hands are doing — in that image the lace is being pulled from nowhere. Fingers merging is becoming rare; an action that does not physically resolve is still common. If the point of the shot is a pair of hands using the thing, film the hands. Failing that, frame above the wrists or cut away before the action completes.
A face that recurs. Identity drifts between generations: features, proportions, clothing and accessories all shift. There is an academic benchmark built specifically to measure this, so it is a known open problem and not something better adjectives fix. There are mechanisms, though. Veo 3.1 takes up to three reference images to hold a person or product steady, and Google’s guidance is to write a fixed character block — a name, a voice style, the features that must not change — and paste it into every prompt in the sequence. Reference mode forces the 8-second duration, so an attempt costs $0.80 on Fast 720p rather than $0.40. What will not do the job is the seed: the Gemini API documentation says seed on Veo 3 models “doesn’t guarantee determinism”, whatever the marketing suggests, and Sora’s characters parameter holds non-human subjects only. If a human face has to recur through a whole video, film it.
Long takes. Coherence decays as a clip runs. The limits vary: Veo generates 4, 6 or 8 seconds, Sora 16 or 20, and Sora will chain six extensions into two minutes. The limit is not the constraint — quality across the take is. Cut before the model starts to wander, and take the middle of a clip rather than the whole of it. The practitioner fix for a longer sequence is to change angle at every join: chaining last frame to first frame for a continuous shot “degrades badly until it looks completely fried by the 4th iteration”, whereas cutting to a different angle makes the model rebuild the scene and resets the decay. Shot, reverse shot, back again. As one of them puts it, “long seamless scenes are not a good idea with AI anyway.”
Object logic and continuity. The failure that has not moved. Things that must connect do not: a strap that goes behind an arm and never comes out, a lace that threads through no eyelet, hardware that changes between one side of an object and the other. This is harder to spot than a garbled sign and it is now where you should be looking first.
Water, cloth and collisions. Physics is the weakest area. Liquid pours wrongly, fabric moves without weight, objects meet without consequence. Choose shots where nothing much interacts.
The voice. Synthetic narration is evenly paced, breathes in the wrong places and never corrects itself. If you are using a voice, use your own clone, which YouTube exempts from disclosure entirely, and write for speech rather than for reading.
Camera grammar. Generated shots tend towards an unmotivated slow push, perfectly smooth, perfectly lit, subject centred. Real footage has weight and mistakes in it. The problem is not that any single shot looks bad; it is that eight of them in a row look like a screensaver.
The practical version of all of this: generated material survives best as short inserts inside footage that is yours. It fails when it is asked to carry the whole thing.
And one thing that does not work, despite being the standard advice: grain. A working colourist’s assessment of generated footage is that collapsed skin tones, waxy faces, smeared texture, banded gradients and clipped highlights “are far too obvious to be fixed by simply adding film grain”. Grain helps generated and filmed material sit together in one grade. It does not repair a bad take, and the fix for a bad take is another take.
The authorship test, which matters more#
This is the one that decides both your monetisation and whether anybody watches twice, and no amount of production quality substitutes for it.
The substitution test. Could your next video be produced by taking this one and swapping the topic? If yes, you have a template, and templated content reproduced at scale with no real author input is precisely what YouTube’s Inauthentic Content policy excludes from monetisation. TikTok’s equivalent language is content with “minimal original input or edits”. Neither policy mentions AI, because AI is not the variable.
The subtraction test. Mentally delete everything from your video that anyone with the same subscriptions could have produced in an afternoon. What is left? A number you measured, an invoice you paid, a client who said something surprising, a thing you got wrong and had to redo, a place you went. If nothing is left, that is the finding. It is fixable, but not by changing tools.
The specificity test. Concrete, checkable detail is what a model cannot supply and an audience cannot get elsewhere. “Email marketing has strong ROI” is available everywhere. “I sent this to 2,140 people, 31% opened it, and eleven bought” is not, and it is the same sentence length.
The why-you test. If a viewer asked why they should hear this from you specifically, is there an answer? It does not have to be credentials. It can be that you did the thing for six months and kept records.
What the audience data actually says#
The evidence here is better than usual, and it does not say audiences hate AI.
A study in the Journal of Retailing and Consumer Services analysed 7,822 YouTube and Reddit comments on Coca-Cola’s AI-generated Christmas campaign. The objection turned out not to be image quality. Viewers inferred a motive, and the motive they inferred was cost-cutting. The same paper found that disclosing AI use improves engagement and purchase intent only when the disclosure also conveys human creative investment; disclose authorship with nothing attached and you amplify the suspicion instead of resolving it.
DoubleVerify’s 2026 study found 43% of North American consumers said a brand’s use of low-quality or uncanny AI content would worsen their opinion of it. The qualifier is doing the work in that sentence. And appetite for AI-generated creator content fell from about 60% in 2023 to around 26%.
Coca-Cola is the cleanest case study because it ran twice. The 2026 version removed the generated humans that had unsettled people in 2024, and the reaction was worse: positive sentiment fell from 23.8% before the campaign to 10.2% after. Fixing the artefacts did not fix the problem, because the problem was that the craft had been replaced on the one asset people cared about.
So the rule that follows from the evidence is narrow and useful. Use these tools where they add something that was not going to exist anyway. Do not use them visibly in place of the thing your audience came for.
Before you publish#
Ten questions. The first four are the ones that matter.
- If I swapped the topic, would this be my next video? If yes, stop.
- What is in here that only I could have put here? Name it out loud.
- Is there a specific number, document, name or date on screen?
- Would I still make this if the tools had not existed? If no, that is worth sitting with.
- Is there any text in a generated shot that I need someone to read?
- Do hands do anything important in a generated shot?
- Does a generated person appear more than once?
- Is any generated take running long enough to drift, and have I trimmed its last half-second?
- Does the disclosure toggle apply, and have I set it? Realistic depiction of a real person, place or event means yes. Unrealistic scenes, filters, effects, production assistance and cloning your own voice mean no.
- If someone in the comments says “this is AI”, is my answer better than silence?
On the last one: the research says a bare admission makes things worse and an explanation of what you actually did makes things better. “The aerials are generated, everything with me in it was filmed in Leeds in March, and the numbers are from my own invoices” is a complete answer and takes one line.
Where this applies#
The artefact list is most useful for short-form, where generation is doing the most work and there is nowhere to hide a bad take. The authorship test is what decides whether a long-form channel earns anything at all, because that is where the monetisation policy actually bites.
For client work, both matter commercially rather than ethically: the brand is buying the judgement to reject the eight takes that look wrong, which is the scarce input. Making video with AI has the pricing and rights side.
And disclosing AI use covers the legal position, including the EU obligation in force since 2 August 2026, which is a separate matter from either of these tests.
The specimen above was generated for this page in a single attempt in September 2026 and is reproduced as evidence, not decoration. One image is not a survey: it shows that two widely-cited tells can come out clean on a current model, not that they always will.
Sources: When AI ads backfire, Journal of Retailing and Consumer Services, 7,822 comments analysed; Marketing Dive for the sentiment figures; YouTube Help for the disclosure boundaries; Face Consistency Benchmark for GenAI Video on character consistency as an open problem; Gemini API Veo documentation for clip durations, reference images and the seed caveat, and OpenAI for Sora durations, extensions and the characters parameter. Techniques and observations attributed to makers and to a colourist are self-reported on public forums, not measured. The artefact list is compiled from current model-limitation surveys and is a description of tools in September 2026, so expect individual items to date. Checked 8 September 2026.